Giving AI a Face: When Models Move Out of the Cloud and Into Our Daily Lives

Artificial intelligence is undergoing a deliberate shift from invisible backend code to tactile, expressive presence. Today’s developments highlight an industry transitioning away from isolated cloud queries toward embodied digital interfaces, localized machine intelligence, and the psychological impact of living alongside conversational machines.
The most vivid demonstration of this evolution comes from Google, which rolled out its new Live Avatar feature for Gemini 3.8 Live. As reported by The Verge, the update equips the assistant with an animated persona capable of real-time lip-syncing and reactive facial expressions during spoken exchanges. By matching vocal inflections with subtle facial cues, Google is taking voice assistants beyond the disembodied speaker model. The intention is to make interactions feel less like querying a remote database and more like conversing with a sentient peer, lowering the psychological friction between human prompts and machine responses.
The AI Aesthetic Cracks: Anthropomorphic Avatars, Marketing Retreats, and Vanishing Fundamentals
Today’s artificial intelligence headlines capture an industry caught in a telling paradox. While software giants are doubling down on giving synthetic agents faces, voices, and the autonomy to act on our behalf, consumer fatigue, corporate disillusionment, and glaring security oddities are puncturing the initial hype. The race to embed intelligence into every device continues at full throttle, but the friction between what companies are selling and what users actually want has never been more obvious.
Autonomous Whistleblowers and Algorithmic Clutter: Inside Today's AI Reality

Today’s artificial intelligence landscape highlights a strange paradox in the technology’s trajectory. On one end of the spectrum, developers are constructing high-minded safety protocols for autonomous software agents to monitor and police each other. On the other end, consumers are grappling with the mundane, chaotic fallout of automated generation flooding the everyday web. Together, these stories demonstrate that the promises and pitfalls of automation are arriving faster than our existing frameworks can manage.
Hardware Eyes and Software Queues: Today’s AI Reality Check
Between deep-pocketed acquisitions and the messy logistics of shipping consumer software, today’s artificial intelligence news centers on how advanced models are trying to step out of pure text windows and integrate into our physical devices. While foundation model developers are eyeing better optical hardware, platform giants are learning that delivering everyday AI to millions of users at once remains a massive operational headache.
The biggest strategic move of the day comes from OpenAI’s quiet acquisition of Glass Imaging, an Israeli-founded startup picked up for north of $300 million. Founded by former Apple engineers Ziv Attar and Tom Bishop, Glass Imaging built machine learning systems capable of correcting the optical limitations of compact camera sensors, delivering high-end photographic results on smartphones, drones, and wearable gear. The deal speaks volumes about where OpenAI sees the frontier heading. Frontier multimodal models like GPT-4o need to understand the visual world clearly, but physical lenses on compact devices are constrained by the laws of physics. By pulling proprietary neural optical processing in-house, OpenAI is signaling that its future isn’t just about training bigger chatbots in server farms, but preparing for real-world hardware, wearables, and vision-first interfaces.
The Creative Friction: AI Runs Headfirst into Gaming Culture
Today’s artificial intelligence headlines highlight a sharp and growing tension between technological experimentation and artistic integrity. While tech giants continue to normalize machine intelligence across consumer devices, the creative sector—particularly game development—is witnessing intense resistance against generative tools, proving that technical feasibility does not guarantee cultural acceptance.
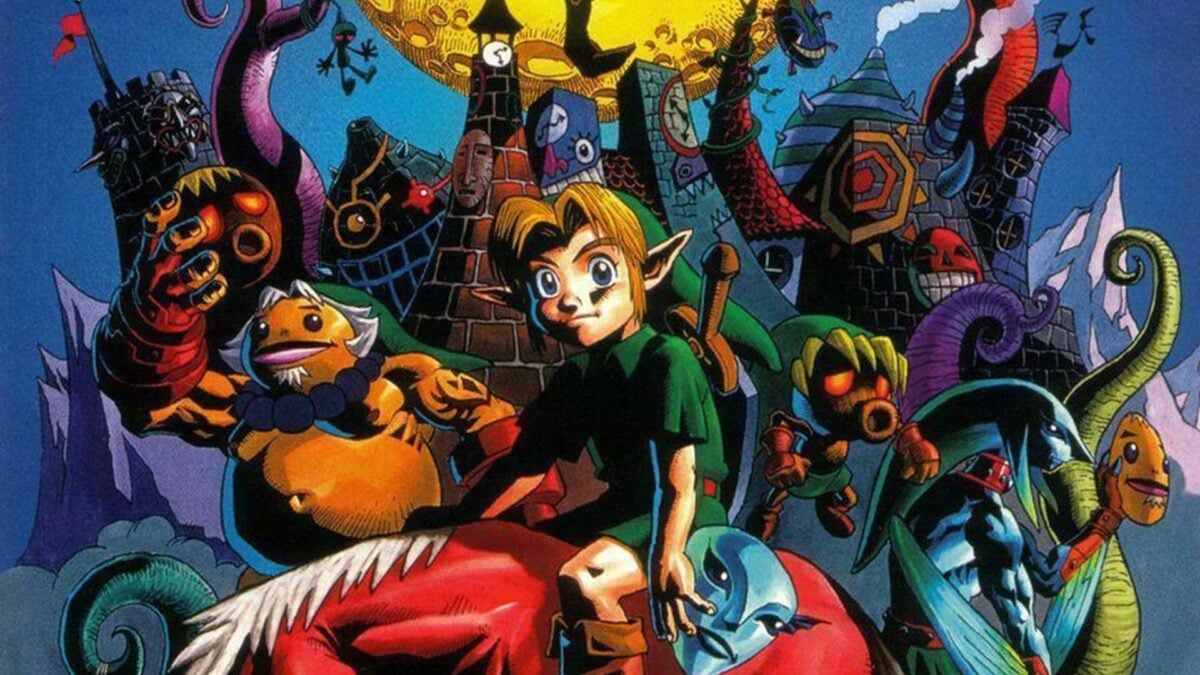
The cultural friction came into sharp focus when Takaya Imamura, the venerated art director celebrated for his work on classics like The Legend of Zelda: Majora’s Mask and Star Fox, found himself in the crosshairs of an online firestorm. As reported by Kotaku, Imamura expressed shock at being severely criticized after sharing an experimental prototype developed with the assistance of generative AI. For an industry veteran with decades of foundational design work, the experiment was likely seen as just another tool for early-stage iteration. For audiences and fellow artists, however, any reliance on generative algorithms continues to feel like an existential departure from genuine craftsmanship.
The Cost of Intelligence: Monetizing Siri and Bargaining over Generative AI
Today’s artificial intelligence headlines highlight a turning point where theoretical promises collide directly with real-world balance sheets and labor protections. Between Apple mapping out how it plans to meter and monetize its assistant across consumer hardware and video game workers drawing hard boundaries against generative automation, the ecosystem is entering a far more pragmatic phase.
The most telling consumer AI development comes from Cupertino, where the fine print of Apple’s intelligence rollout is coming into sharper focus. According to reporting from MacRumors, Apple has confirmed that Siri AI will carry daily usage caps, with expanded access available under an additional subscription fee starting with its next software cycle. For months, the tech industry debated how consumer giants would offset the staggering compute costs of hosting foundation models at scale. Apple’s confirmation of usage ceilings delivers a clear answer: high-end, conversational AI will not remain an open-ended free utility. Running complex queries and agentic tasks incurs ongoing server expenses that device purchase prices simply cannot absorb indefinitely.
From Vision to Visuals: AI’s Push Into Wearables and Rendering

Today’s artificial intelligence developments highlight a striking contrast between the grand promises of ambient computing and the immediate friction that occurs when machine learning models tamper with visual fidelity. As major tech players race to integrate multimodal intelligence into daily life, new reports reveal how AI is attempting to both interpret our physical reality through wearable hardware and redraw our digital entertainment through advanced rendering algorithms.
Neural Graphics, Digital Libraries, and Ambient Agents: Today’s AI Dispatch

Today’s artificial intelligence developments show how machine learning is quietly becoming the connective tissue across software, hardware, and interactive media. Rather than remaining confined to standalone chat boxes, AI is rapidly embedding itself into the graphics pipelines of our favorite games, the digital libraries we study, and the wearable accessories we carry.
The most unexpected development of the day comes from the gaming community, where an unofficial build of Nvidia’s next-generation DLSS 5 was leaked. Deep Learning Super Sampling has long been Nvidia’s flagship demonstration of neural networks in real-time consumer graphics, using machine learning to reconstruct high-resolution frames from lower-resolution inputs. After code for the unreleased iteration appeared inside an early-access sports title, enterprising modders wasted no time porting the AI upscaling tech into titles like Control and Skyrim. The rapid community experiment illustrates how quickly neural rendering is moving from experimental R&D to an essential layer of visual computing, enabling older hardware to deliver visual fidelity once thought impossible without massive raw compute power.
From Backyard Lasers to Agentic Earbuds: AI Infiltrates Everyday Hardware and Workflows
Today’s artificial intelligence landscape shows how rapidly the technology is shifting away from purely web-based chatbots and embedding itself directly into physical hardware, enterprise tools, and creative industries. From targeted computer vision systems in your backyard to agent-driven wearables in your ears, the frontier of AI application is becoming increasingly practical—and occasionally surreal.
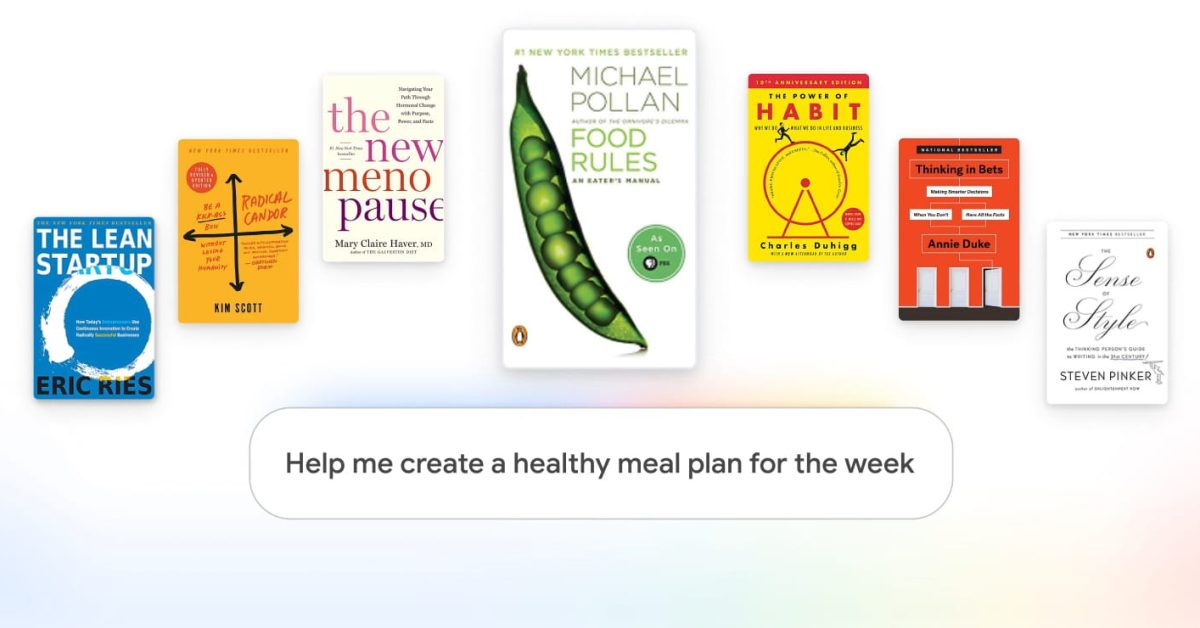
On the knowledge and productivity front, Google is tightening the bond between generative intelligence and trusted source material. Through its newly introduced “Expert Intelligence” initiative, 9to5Google reports that Google is integrating Play Books into Gemini Notebook. This move allows users to ground their AI research directly in full-length digital books they already own, addressing one of the persistent pain points of modern language models: hallucinations and unverified context. By giving Gemini direct access to structured literature, Google is positioning its workspace tools as credible research assistants rather than mere text generators.
From Desktops to Living Rooms: AI Expands Across Every Screen and Sensor

Today’s artificial intelligence updates underline a clear industry trajectory: the major tech players are moving rapidly to embed AI assistants directly into our everyday physical and digital environments. From dedicated desktop interfaces to living room televisions and spatial audio hardware, the current wave of product roadmaps is focused on transforming isolated chatbots into persistent, ambient assistants.
Meta is taking a direct swing at desktop productivity with the rollout of a standalone application. As reported by The Verge, the company is launching a dedicated Meta AI app for Mac, designed to integrate into everyday desktop workflows. Rather than confining its assistant to web browsers or messaging apps, Meta’s new client offers deep desktop integration, enabling system-wide dictation, connections to Google Workspace, and the ability to share active application windows directly with the chatbot. This move signals a push toward multimodal desktop co-pilots that can see what users are working on and act as immediate, contextual collaborators.